Independent verification for teams shipping with AI
Coding agents write code faster than ever — but they cannot grade their own work. Agentiqa drives a real browser to verify complex user flows before anything reaches production. No manual click-throughs, no broken releases.
Independent verification
Coding agents suffer from context bias and assertion gaming. Agentiqa tests as an independent observer in a real browser — completely outside your agent’s context.
Dual-trigger workflow
Run an instant verification check right from Claude Code or Cursor before you commit — and let unattended suites guard your staging environment every night.
Evidence, not flaky scripts
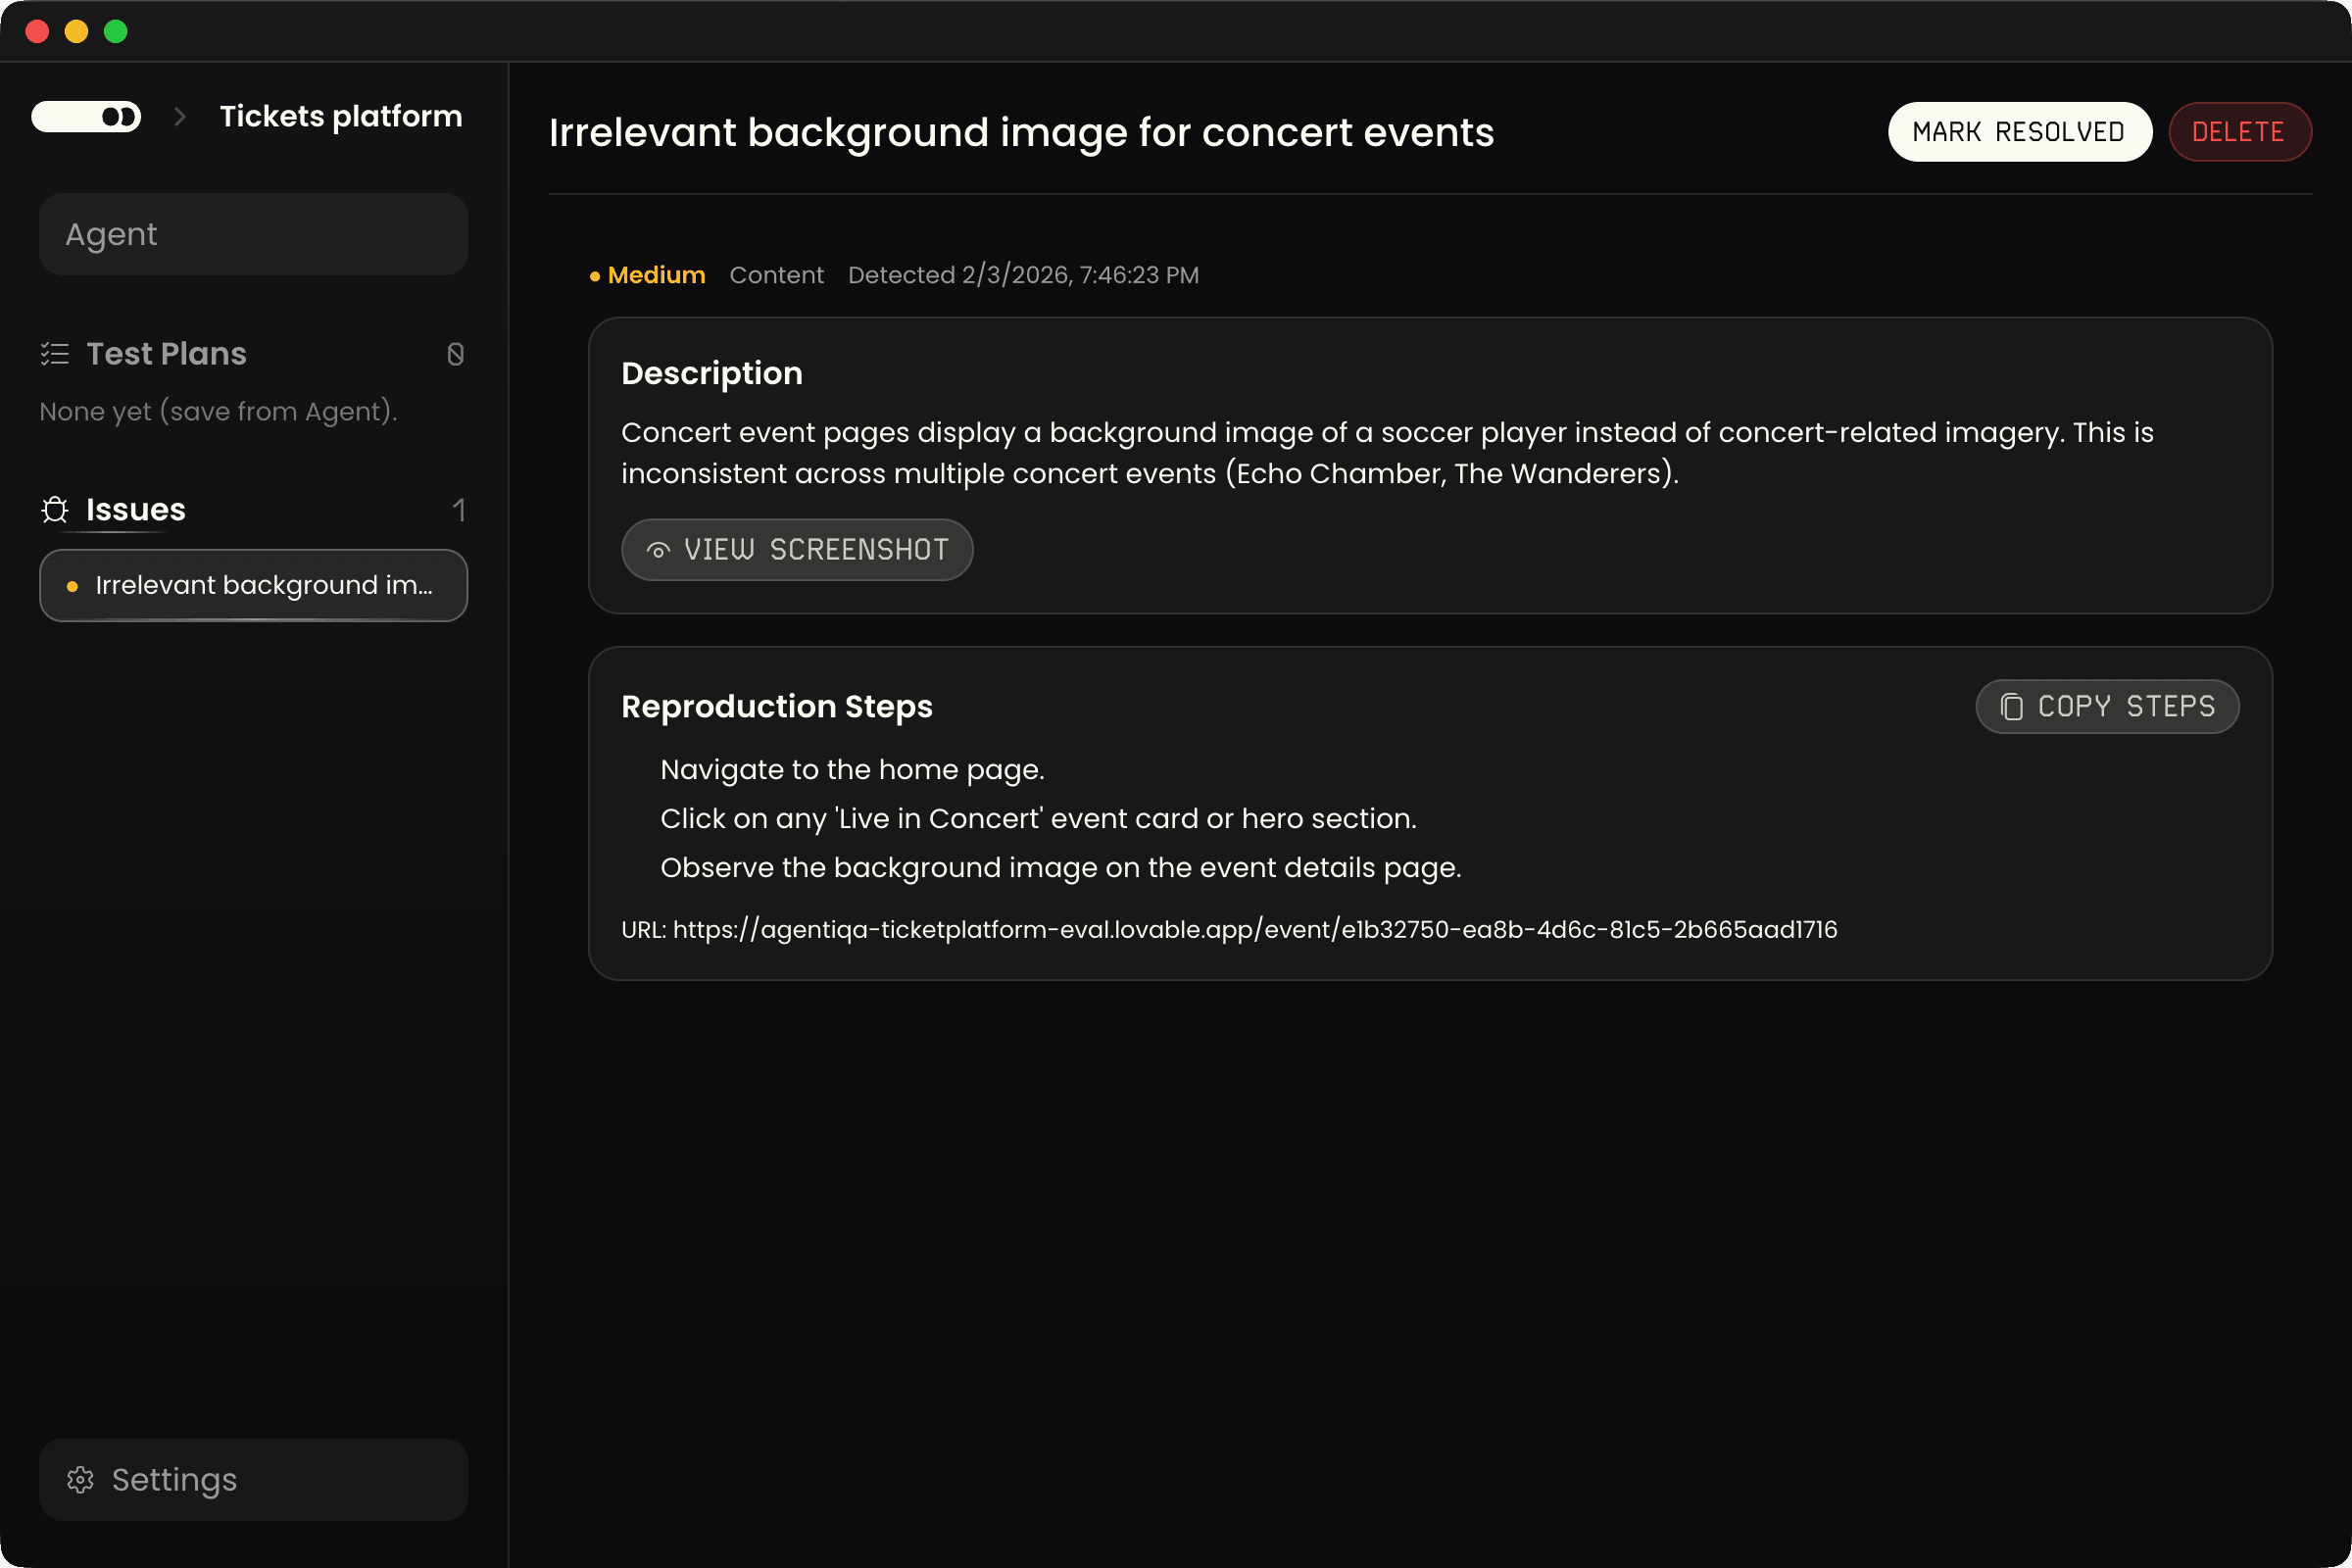
No fragile selectors to debug. Every finding arrives with video recording, screenshots, and step-by-step reproduction ready to feed straight back into your coding agent.
Enterprise security
Credentials never enter the model context. No source-code access required.
SOC 2 in progress · View live Trust Center
Finish your feature
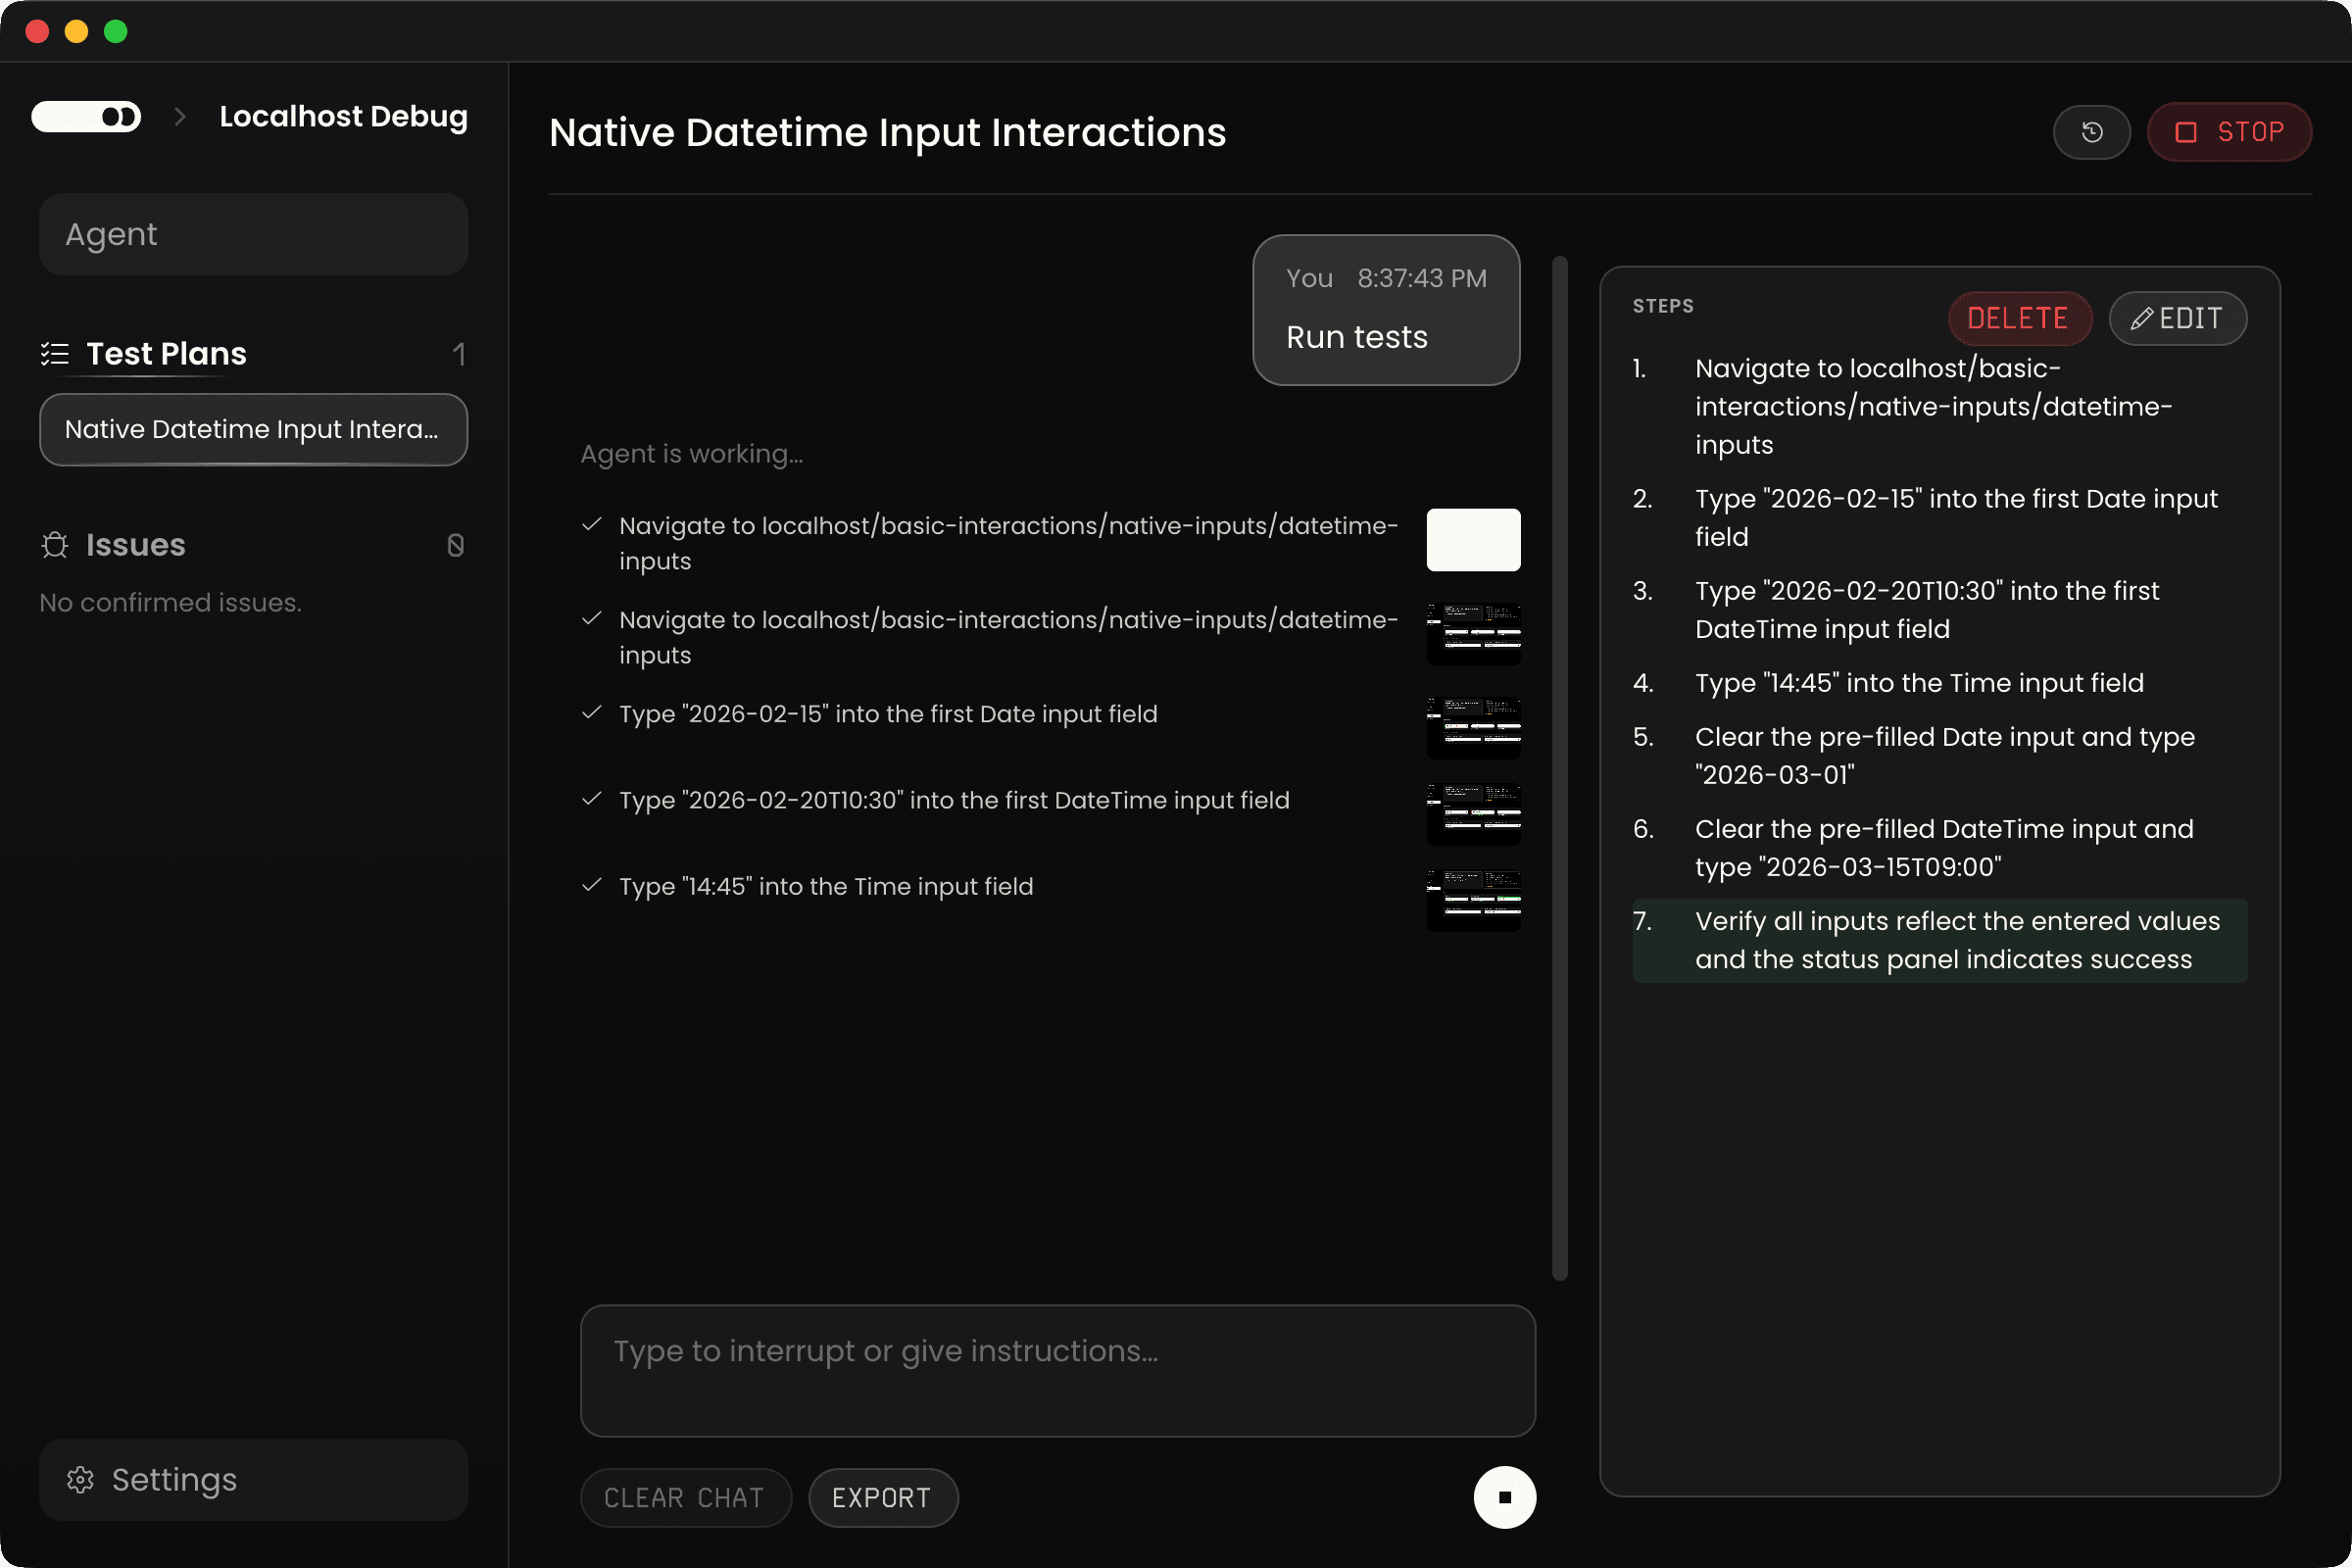
Trigger a check from your terminal or directly inside Claude Code or Cursor. No local browser checkout, no writing Playwright scripts from scratch.
Agentiqa navigates real user journeys
An independent agent executes your scenario in a real browser — handling multi-step state, authentication, and external integration points.
Fix with clear visual proof
If something breaks, you don’t guess from stack traces. You get a video replay and structured reproduction steps ready to consume and fix.
Remembers your product
Project memory carries context across runs — flows, quirks, past bugs — so every run starts smarter than the last.
One hub for testing
Test plans, run history, and findings live in one place — a QA hub for teams without a QA department.
Regressions over time
Every run is recorded with its findings, so you can see what broke, when, and how often across releases.
Remembers your product
Project memory carries context across runs — flows, quirks, past bugs — so every run starts smarter than the last.
One hub for testing
Test plans, run history, and findings live in one place — a QA hub for teams without a QA department.
Regressions over time
Every run is recorded with its findings, so you can see what broke, when, and how often across releases.
Ways to use Agentiqa
Fits the way your team already ships.

CLI
A quality gate for your CI/CD pipeline.
- GitHub Actions, GitLab, CircleCI, Buildkite
- Service-key auth, JSON output, exit codes
- Claude Code / Cursor / Codex plugins

Web
Cloud runs for your whole team, no setup needed.
- Cloud execution, nothing to install
- Parallel test-plan runs
- Learns your app across runs
- Shared access across your team

Desktop App
Local-first evaluation on your own machine.
- Test localhost & internal builds
- Your app and data stay on your machine; only model calls go out
- Included with Starter — 10 runs each month, credits to scale
What is agentic testing?
AI agents execute testing goals and surface findings in a real browser — not just static scripted steps.
Why can't my coding agent just write and run its own tests?
Coding agents suffer from context bias, weaken assertions when tests fail, and miss cross-system side effects. Agentiqa provides an independent verification layer that tests your product from the outside without relying on the agent's internal shortcuts.
When do teams run Agentiqa?
In two key moments: immediately after a coding session in Claude Code or Cursor to verify the feature you just built, and overnight as an unattended regression suite across your environment.
What kind of issues does it catch?
Functional and UX regressions — broken states, visual glitches, responsive problems — each reported with severity, category, video recordings, and step-by-step reproduction your team can act on.
How does onboarding work?
Company plan engagements include a warm start: we set up and maintain your suite with you for the first month, then any engineer or QA runs it.
Can we run it locally and in our CI?
Yes — run local-first for localhost and internal builds, or wire the CLI into your CI as a quality gate. GitHub Actions and other major providers are auto-detected.
How does it protect our code and secrets?
The agent tests from the outside, so it never needs repo access. Credentials are stored encrypted and typed by name — the model only ever sees placeholders.
How is it different from AI + browser?
For a one-off check, that works. It stops working when testing must repeat and be trusted: a raw prompt loop wanders, reports "looks fine" without proof, and reads your passwords. Agentiqa is that idea built into a QA system — supervised runs, recorded step-by-step evidence, plans that re-run in CI and in parallel, credentials the model never sees, and testing context that compounds.
“With Agentiqa, our agents build and iterate on complex end-to-end test plans autonomously. Running them daily, we proactively catch regressions across all our systems. In the first week alone, Agentiqa surfaced five real production bugs we’d never have caught without a full-time QA team.”